


What SLNG does
The LLM router sits between ElevenLabs and your model
Fewer model calls per conversation.
Simple turns
Confirmations, greetings, consent speech, hold responses handled locally.
Complex turns
Reasoning, decision-making, ambiguous input go to your model as normal.
The result
Fewer LLM calls. Lower cost. Same output quality.
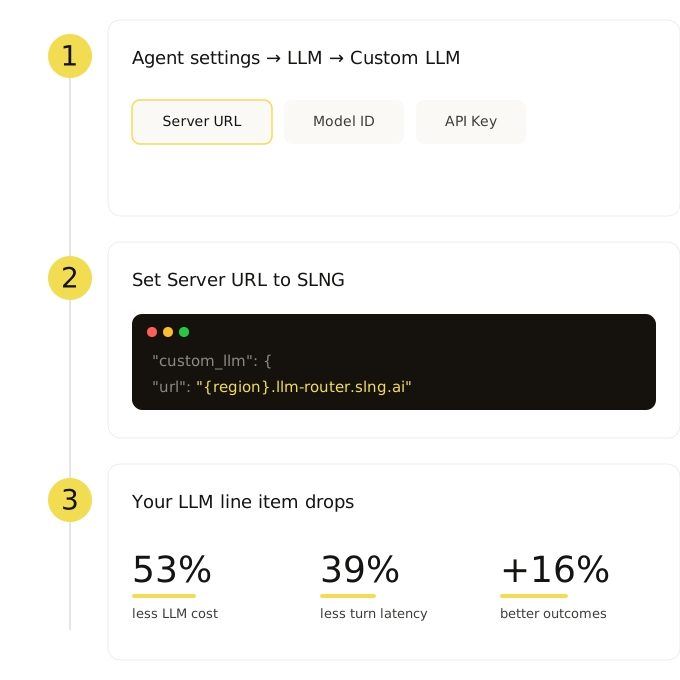
One change in your agent config
Same voice. Same agent logic. Same plan.
1"custom_llm": {
2  "url": "{region}.llm-router.slng.ai"
3}Adaptive Execution layer
Keep your pipeline. Add the execution layer
The perfect execution path for every turn.
LLM routing
Per-turn model selection and cost optimization.
PII redaction
Personally identifiable data stripped before it leaves the hub.
TTS smart caching
Repeated TTS responses served from cache. Provider never gets called.

Compliance and security


Getting started
Live instantly. Results within 24hrs
Swap the URL in your agent config. We show you the numbers against your current LLM costs.
1. Get your SLNG key
Sign up at app.slng.ai. Get your API key.
2. Update your ElevenLabs config
Agent settings → LLM → Custom LLM → set Server URL
3. See the results
Give it 24 hours. Your dashboard shows LLM cost, latency, and quality vs. baseline.
How does the Context router reduce cost?
The Context router evaluates each turn against the call context. Simple turns that don't need your model are handled locally. Only complex turns go to your LLM. Result: fewer model calls, lower cost, same conversation quality.
How much does it cost?
The SLNG Execution layer costs US$ 0.001 per agent minute.
Does this replace ElevenLabs?
No. ElevenLabs handles voice. SLNG handles the LLM layer underneath.
Is SLNG data-compliant?
SLNG is ISO 27001 and SOC 2 Type II certified. HIPAA compliant. GDPR compliant. PII redaction built in.
Do I need to change my ElevenLabs plan?
No. SLNG is a separate service. No changes to your plan, tier, or payment method.
How does latency improve?
Simple turns skip the LLM round-trip entirely. 39% less turn latency on average.
Can SLNG handle STT and TTS too?
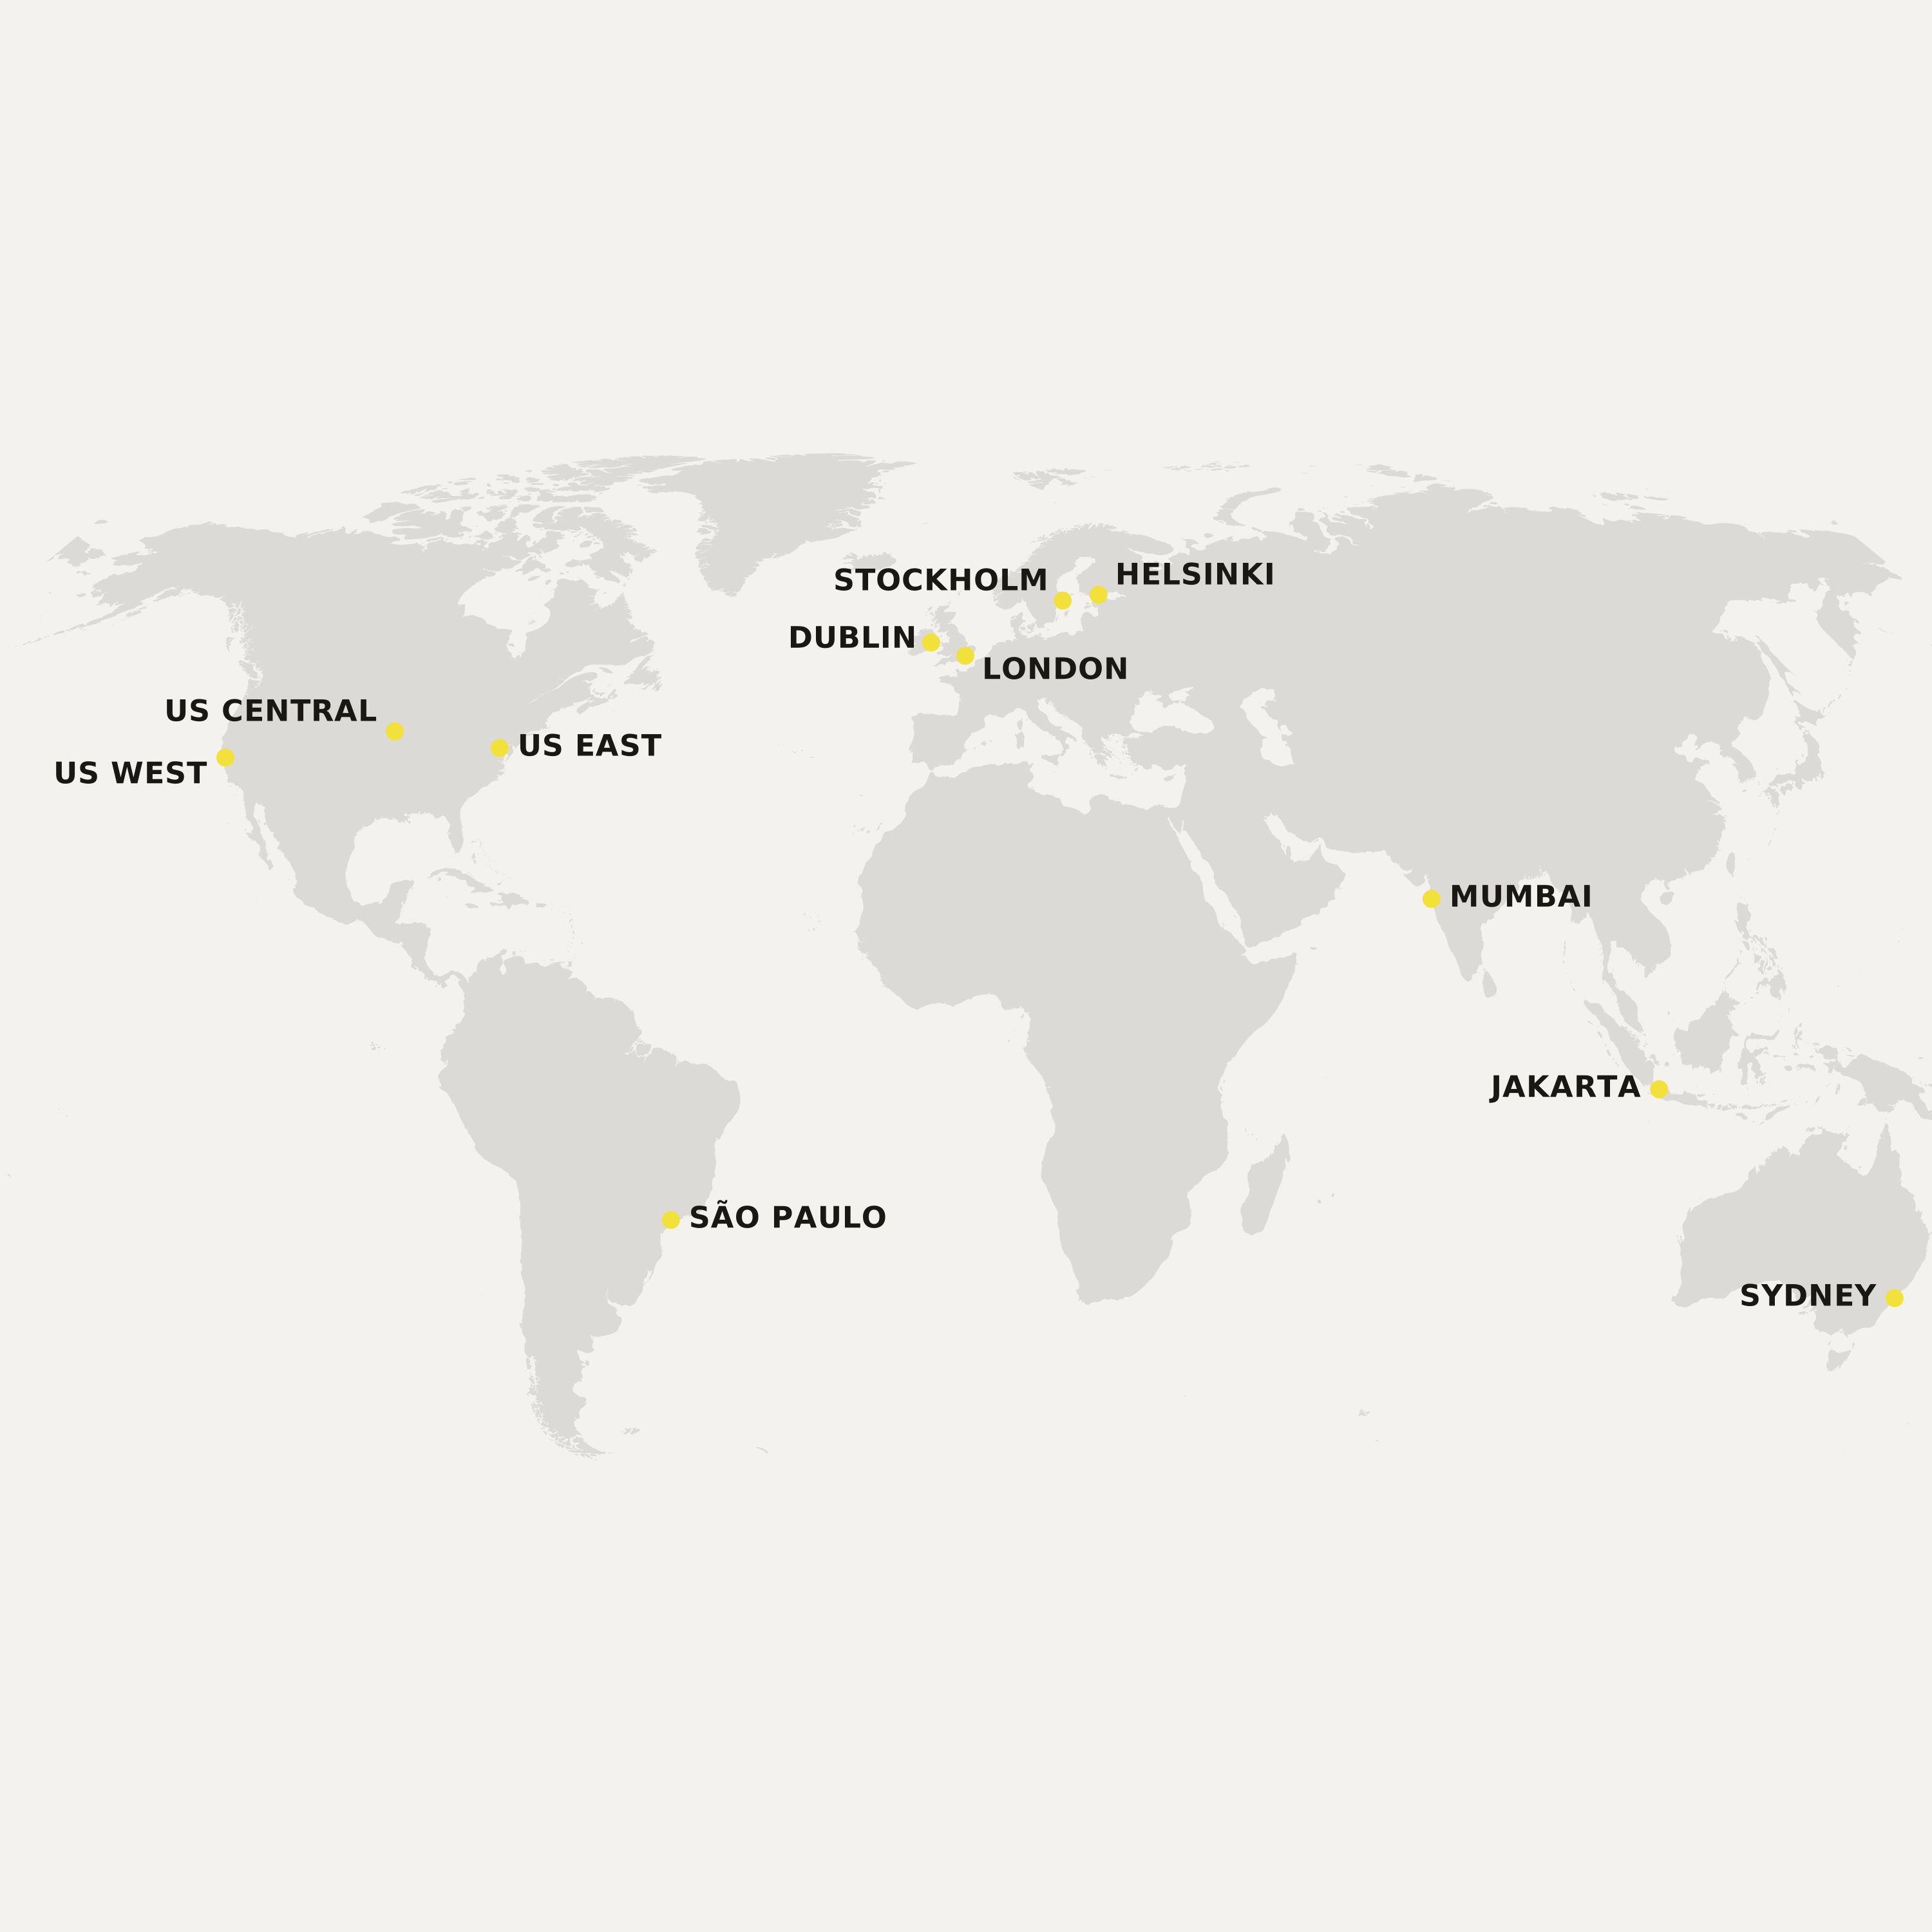
Yes. 30+ models across STT and TTS, running in 11 regions. https://docs.slng.ai/models


