

Use cases
Pricing tailored to your use case
Tap a layer to switch it between SLNG and your own keys
Execution Layer only
Optimise your existing agent
Keep your orchestrator, STT, LLM, and TTS. SLNG adds the execution layer — cache, routing, governance, marking.
- Execution Layer+ US$ 0.001
US$ 0.001/ agent minute
Continuous optimization
The Execution layer stacked between your orchestrator and your models. Running locally in Mumbai.


Agentic voice
From a file to a live call, without opening a dashboard
Your coding agent writes the file, validates it against your rules, compiles it and deploys it through the API, with SLNG routing every call locally in India.

Define
One UNMUTE file holds the whole agent. Prompt, models, tools, channels. Your coding agent writes it, you review it like any other code.

Govern
A saved manifest sets your company's rules: which models and providers, which languages and regions, which deployment targets and tools.

Compile and ship
Violations fail at compile, not on a call. The same package targets Pipecat, LiveKit or SLNG, then deploys, versions and rolls back through the API.
How much does SLNG cost in India?
US$ 0.001 per agent minute. STT, LLM, TTS models and Orchestration are add-ons. Each US$ 0.003 per agent minute with model costs included. No contracts, no minimums.
How is SLNG different from calling Deepgram or OpenAI directly?
The SLNG Execution layer sits between your orchestrator and your models. You keep your existing providers. The execution layer adds LLM routing, smart caching, PII redaction, and analytics, reducing cost and latency on every call. Running in Mumbai means no round-trips to US servers.
What models run in Mumbai?
Sovereign-hosted STT and TTS models on local compute. LLMs available via BYOK, bring your existing OpenAI, Anthropic, or other provider keys. Full model list in the docs.
Can I bring my own model API keys?
Yes. BYOK is the default. Bring your existing OpenAI, Anthropic, Deepgram, or ElevenLabs keys. The SLNG Execution layer routes through them, adding routing, caching, and observability without changing your provider contracts.
Is SLNG suitable for regulated environments?
Yes. SLNG enforces region and country rules at runtime. Enterprise plans add residency, retention, auditability, and SLA-backed guarantees for regulated workloads.
Does my data leave India?
No. Calls routed to ap-south-1 are processed on physical GPU hardware in Mumbai. Audio stays in-jurisdiction. Every call is logged with region, provider, and timestamp.
Does my voice AI data stay in-region?
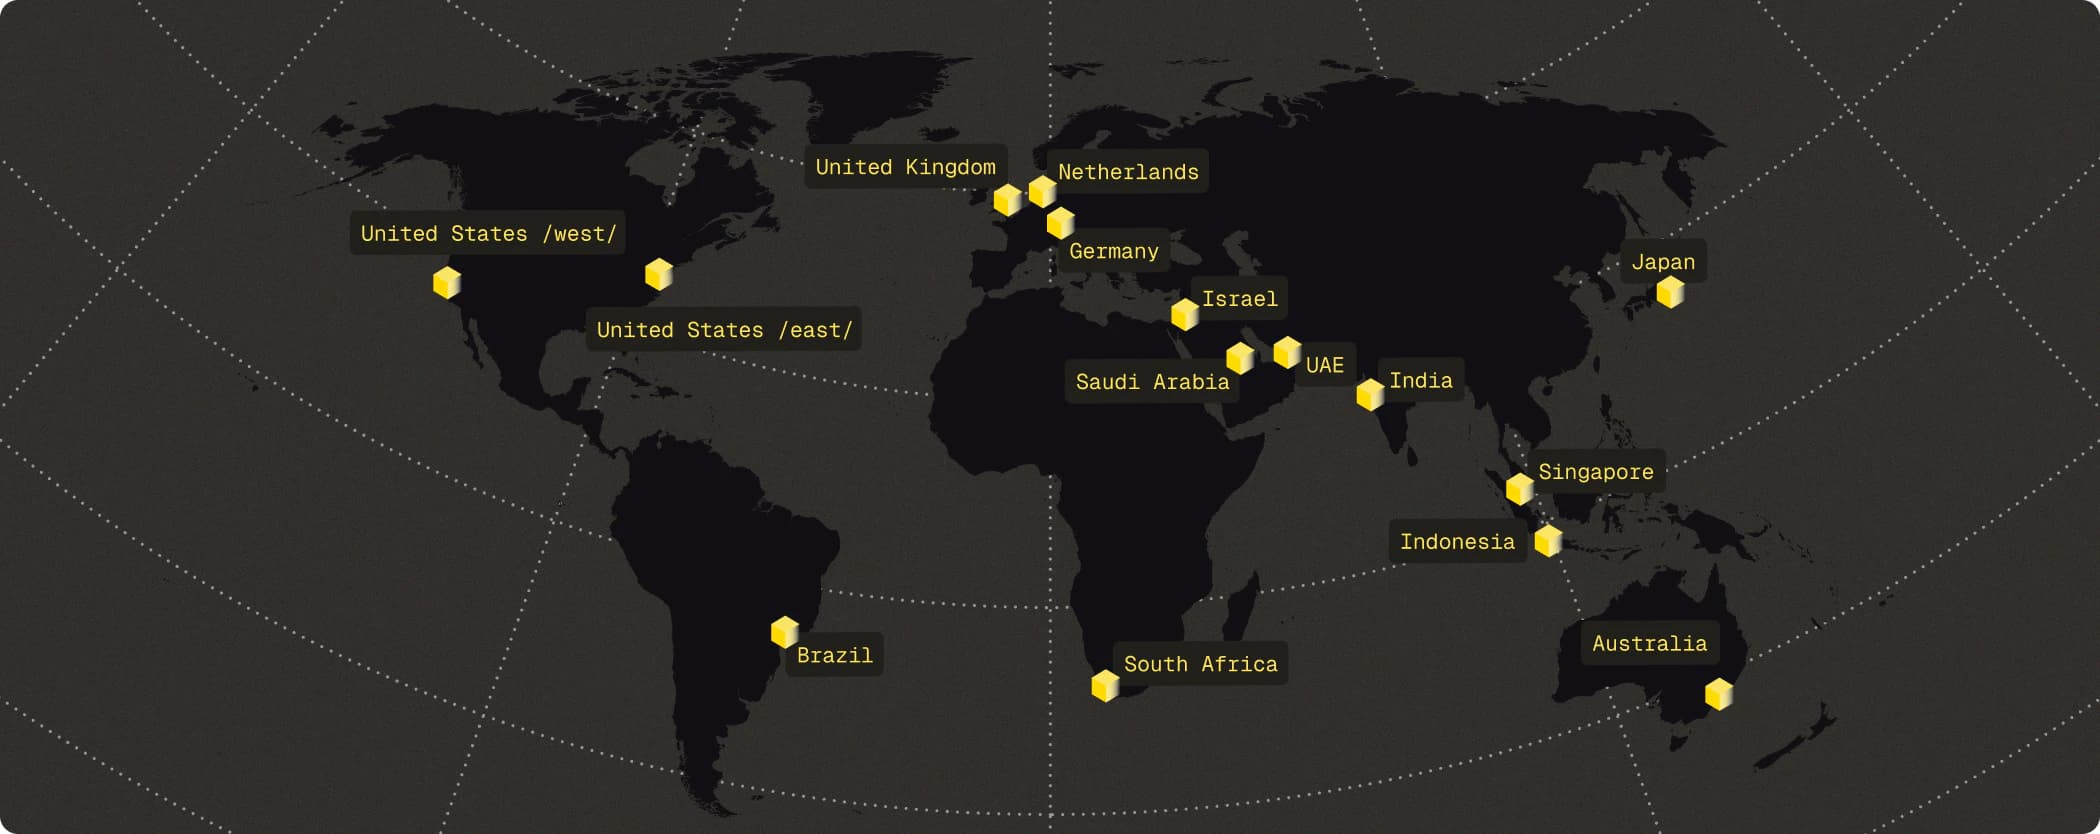
Yes. Audio processed in a region stays in that region. Every call is logged with region, provider, model, and timestamp. You swap your base URL to the region of your choice.


