Deepgram
Setup
- 1Open Agent config
- 2Set the LLM provider to a custom endpoint
- 3Enter your SLNG URL and key
UNMUTE// is LIVE. An open standard for declaring voice agents. HERE
ISO 27001 · HIPAA · GDPR · SOC 2 Type II
Your agent, optimized end to end. Lower latency, lower cost, same stack.
39%
Less turn latency
53%
Less model costs
Works with your platform
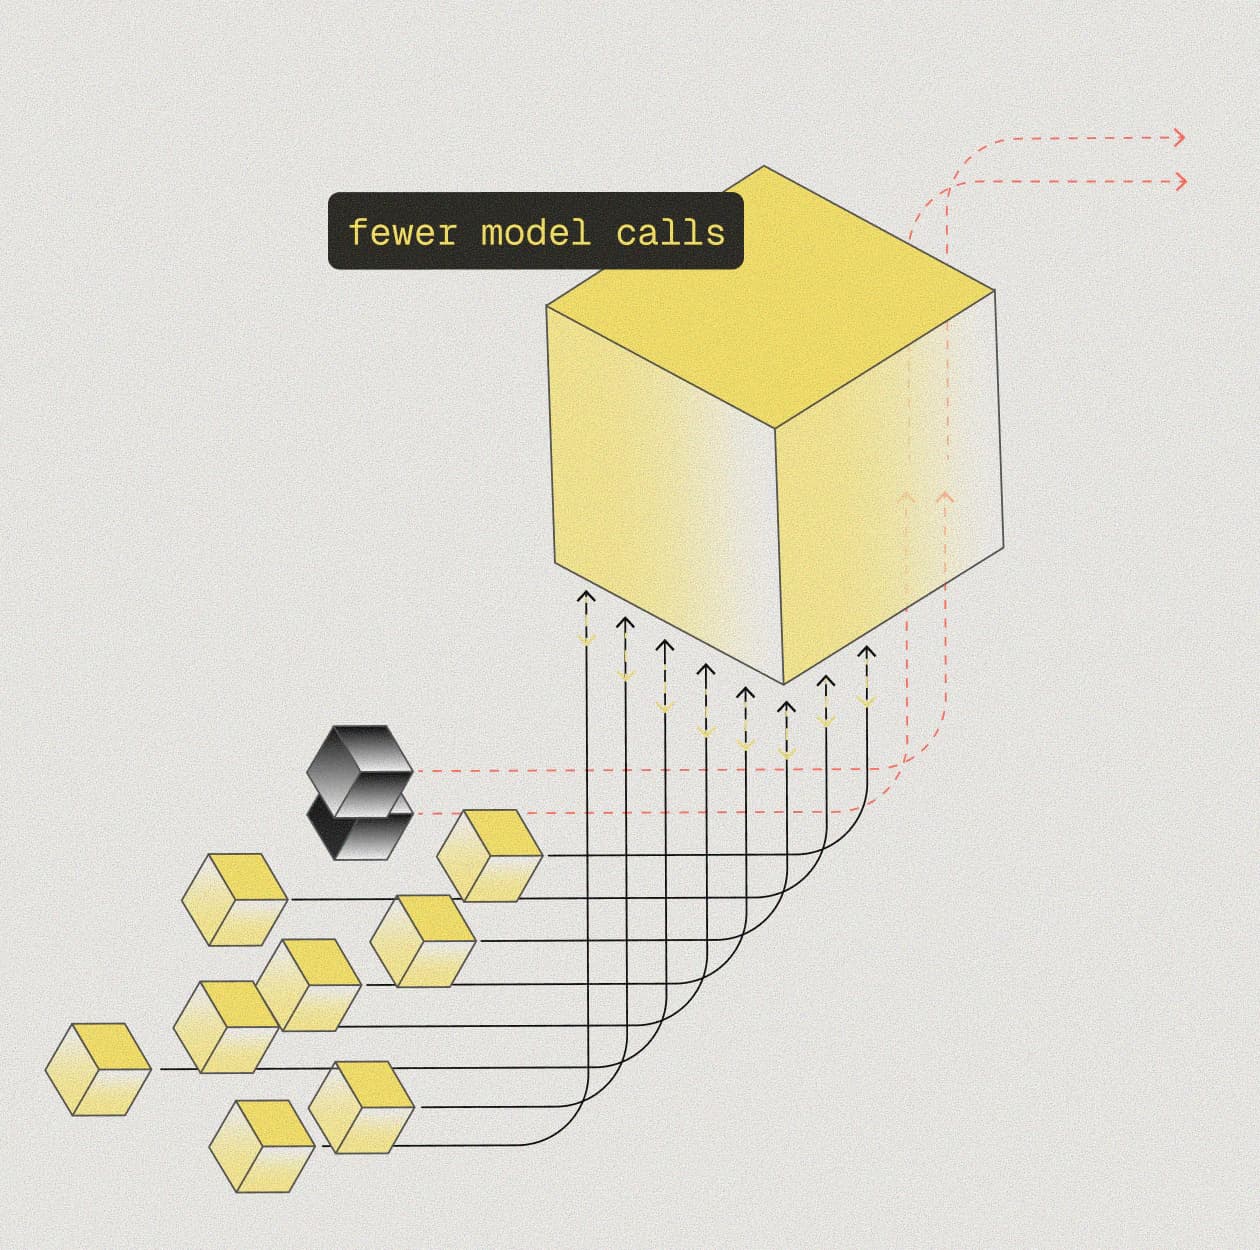
Context router
Not every turn needs your LLM
Fewer LLM calls. Lower cost. Better output quality.
Simple turns
Confirmations, greetings, consent speech, hold responses handled locally.
Complex turns
Reasoning, decision-making, ambiguous input. These get full context and go to your model as normal.
TTS optimization
Lower TTS costs without changing your voice
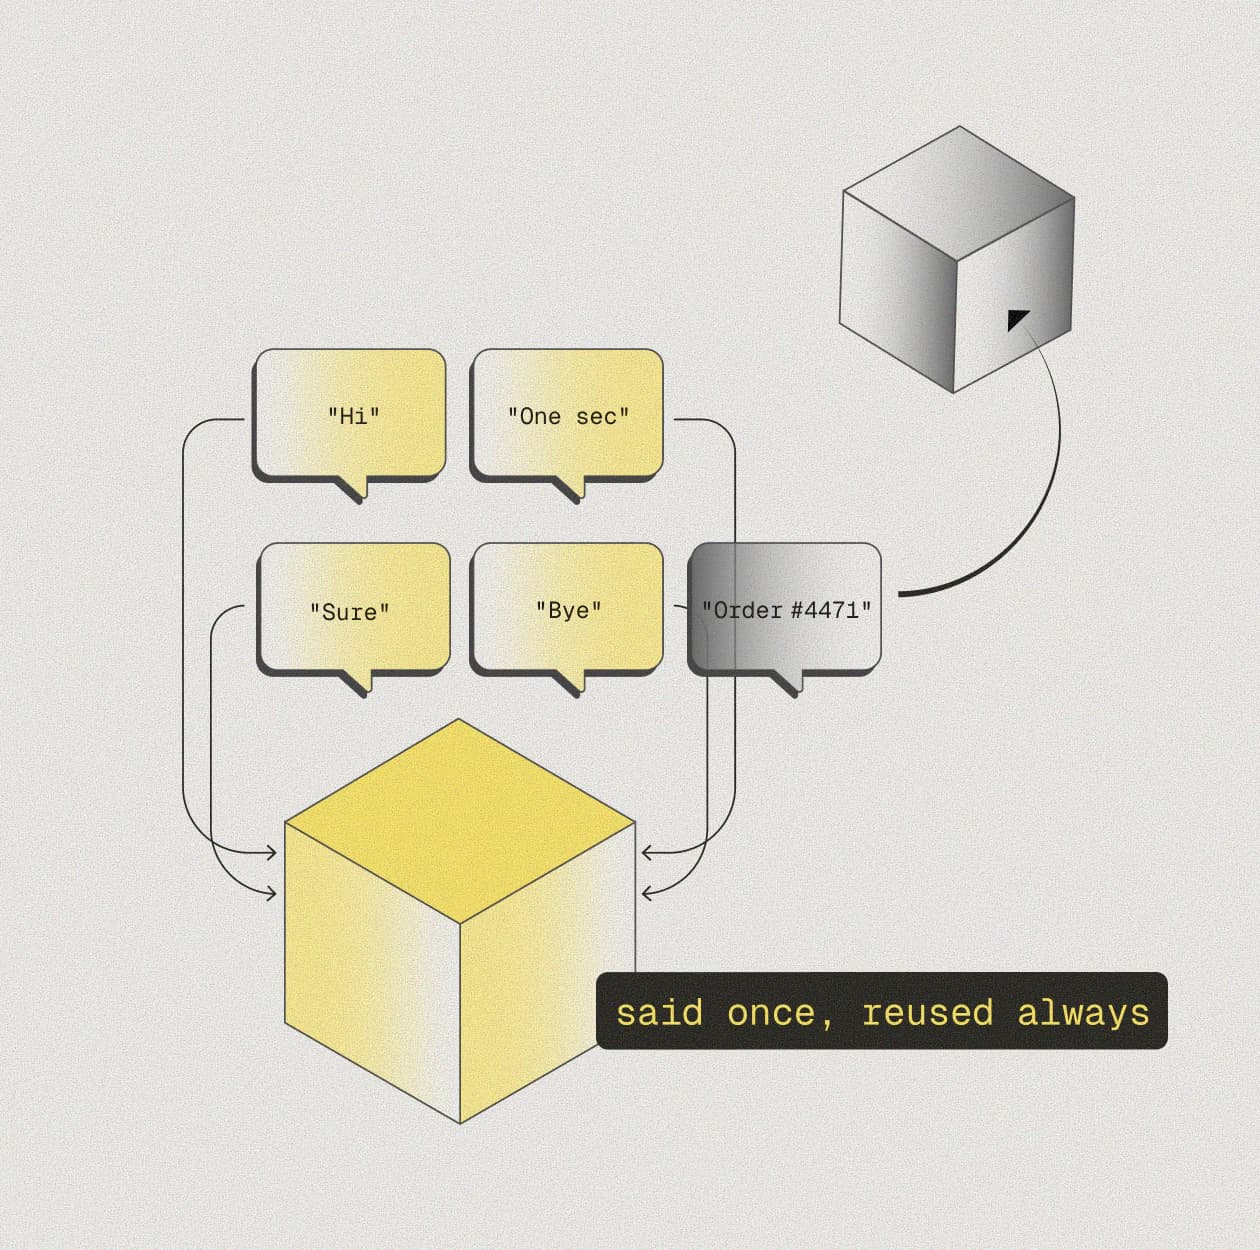
Route your TTS through SLNG. Repeated sentences served from cache. The provider never gets called.
Full cost every time.
The greeting your agent has said ten thousand times costs the same as the first time it said it.
Cache hit. Provider skipped.
Same voice, no synthesis call, no provider charge. Cache miss = passes through on your key. Nothing else changes.
Getting started
Live instantly. Results within 24hrs
Swap the URL in your agent config. We show you the numbers against your current LLM costs.
1. Get your SLNG key
Sign up at app.slng.ai. Get your API key.
2. Point to SLNG //
Set the LLM endpoint to SLNG's URL + your SLNG key. Add TTS the same way when you're ready.
3. See the results
Give it 24 hours. Your dashboard shows LLM cost, latency, and quality vs. baseline.
How does the Context router reduce cost?
The Context router evaluates each turn against the call context. Simple turns that don't need your model are handled locally. Only complex turns go to your LLM. Result: fewer model calls, lower cost, same conversation quality.
Does SLNG work with my agent platform?
If it has a custom LLM field or accepts an OpenAI-compatible endpoint, yes. ElevenLabs, Deepgram, Vapi, Vocode, Bolna, Voiceflow confirmed.
Does SLNG cache TTS audio?
Yes. When your agent repeats a sentence, SLNG serves the cached audio directly. The TTS provider never gets called. Same voice, no synthesis, no provider charge. Cache miss passes through on your key and gets cached for next time.
Do I need to change my TTS provider?
No. Route your TTS through SLNG. Your existing provider key, voice, and settings work unchanged.
Do I need to change my voice or STT provider?
No. SLNG only touches the LLM layer. Your voice, your STT, your platform stay the same.
How much does it cost?
The SLNG Execution layer costs US$ 0.001 per agent minute.
Is SLNG compliant with GDPR?
GDPR compliant. ISO 27001 and SOC 2 Type II certified. HIPAA compliant. Details at trust.slng.ai.
Define. Govern. Execute.