


Continuous optimization
Between your orchestrator and your models. Running locally in the US.
One header
Add X-Region to any API call. No change to your orchestrator, your models, your agent logic.
1curl -X POST https://api.slng.ai/v1/llm \
2  -H "Authorization: Bearer $SLNG_API_KEY" \
3  -H "X-Region: us-east-1" \
4  -d '{
5    "model": "gpt-4o",
6    "messages": [{"role": "user", "content": "..."}]
7  }'
Compliance and security


Execution layer in the US
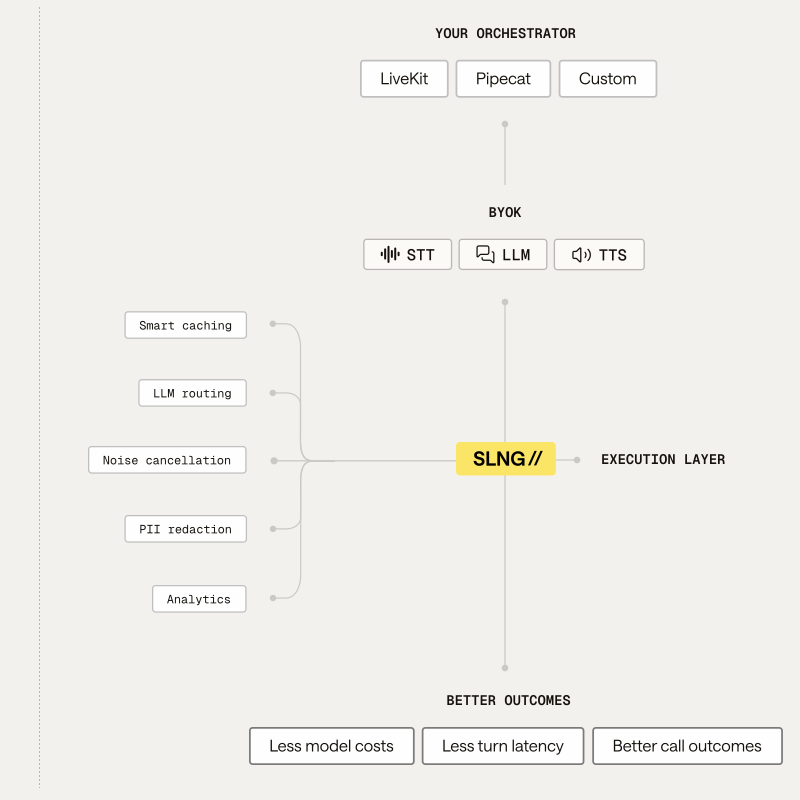
Keep your pipeline. Add the execution layer
Continuous cost and latency reduction.
Keep your orchestrator
Livekit, Pipecat, custom. Your application code stays the same.
Keep your LLM
Keep your existing model and provider. SLNG routes, caches, and reduces cost on every call.
Keep your STT & TTS models
Bring your existing contract and provider. Or choose from SLNG 30+ model catalogue.
Getting started
Live instantly. Results within 24hrs
Send your existing call flow. We run it locally in the US and show you the numbers against your current setup.
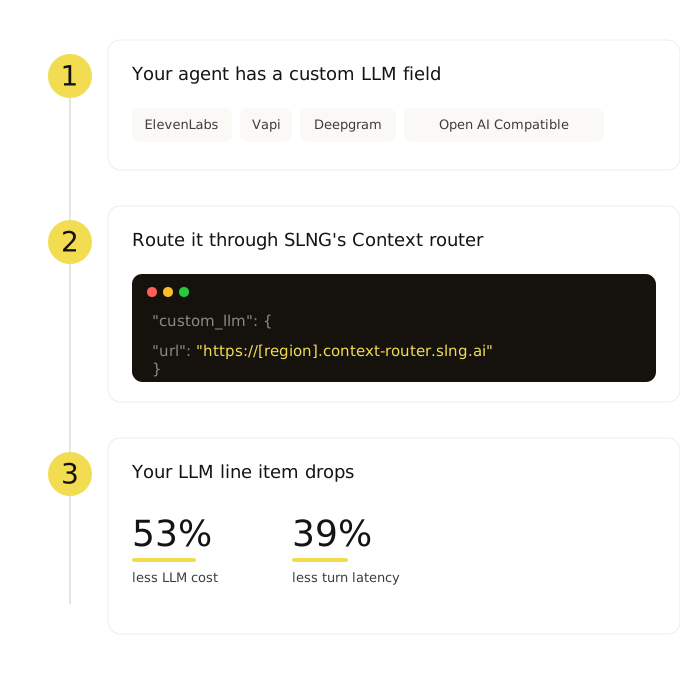
1. Add your keys
Bring your own keys for STT, LLM, and TTS. We never see your credentials.
2. Point to SLNG //
Direct your orchestrator to SLNG endpoints for STT, LLM, and TTS.
3. See the results
Give it 24 hours. Your dashboard shows savings, latency, and quality vs. baseline.
Can I bring my own model API keys?
Yes. BYOK is the default. Bring your existing OpenAI, Anthropic, Deepgram, or ElevenLabs keys. The SLNG Execution layer routes through them, adding routing, caching, and observability without changing your provider contracts.
Is SLNG suitable for regulated environments?
Yes. SLNG enforces region and country rules at runtime. Enterprise plans add residency, retention, auditability, and SLA-backed guarantees for regulated workloads.
How much does SLNG cost in the US?
US$ 0.0033 per agent minute for the execution layer. Add STT or TTS for US$ 0.0033 each. No contracts. No minimums.
What does the SLNG execution layer run in the US?
LLM routing, smart caching, PII redaction, transcripts, and analytics across three US hubs.
What models run in the US?
STT: Deepgram Nova 3, Deepgram Nova 3 Medical, Soniox STT AI. TTS: Rime Arcana, Cartesia Sonic, Murf AI Falcon, Soniox TTS RT, Deepgram Aura 2. SLNG-hosted or bring your own keys.
Does my data leave the US?
No. Routing enforces data residency at the infrastructure level. Audio stays in the US.
Is SLNG HIPAA compliant?
Yes. SLNG is HIPAA compliant with BAA available. ISO 27001 certified. SOC 2 Type II in audit. Details at trust.slng.ai.


