


Built to run with your stack
Agent accelerator
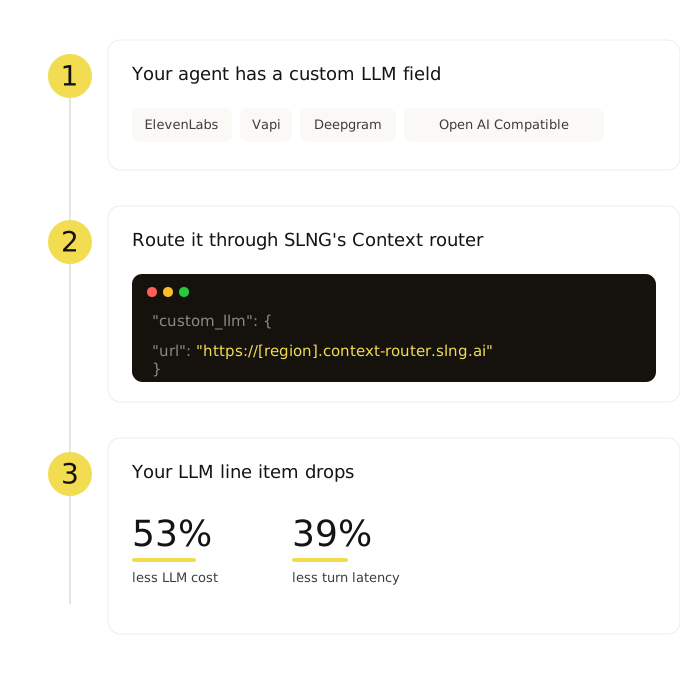
Not every turn needs your LLM
Fewer model calls per conversation.
Simple turns
Confirmations, greetings, consent speech, hold responses handled locally.
Complex turns
Reasoning, decision-making, ambiguous input go to your model as normal.
The result
Fewer LLM calls. Lower cost. Same output quality.
Insurance voice agents running on SLNG
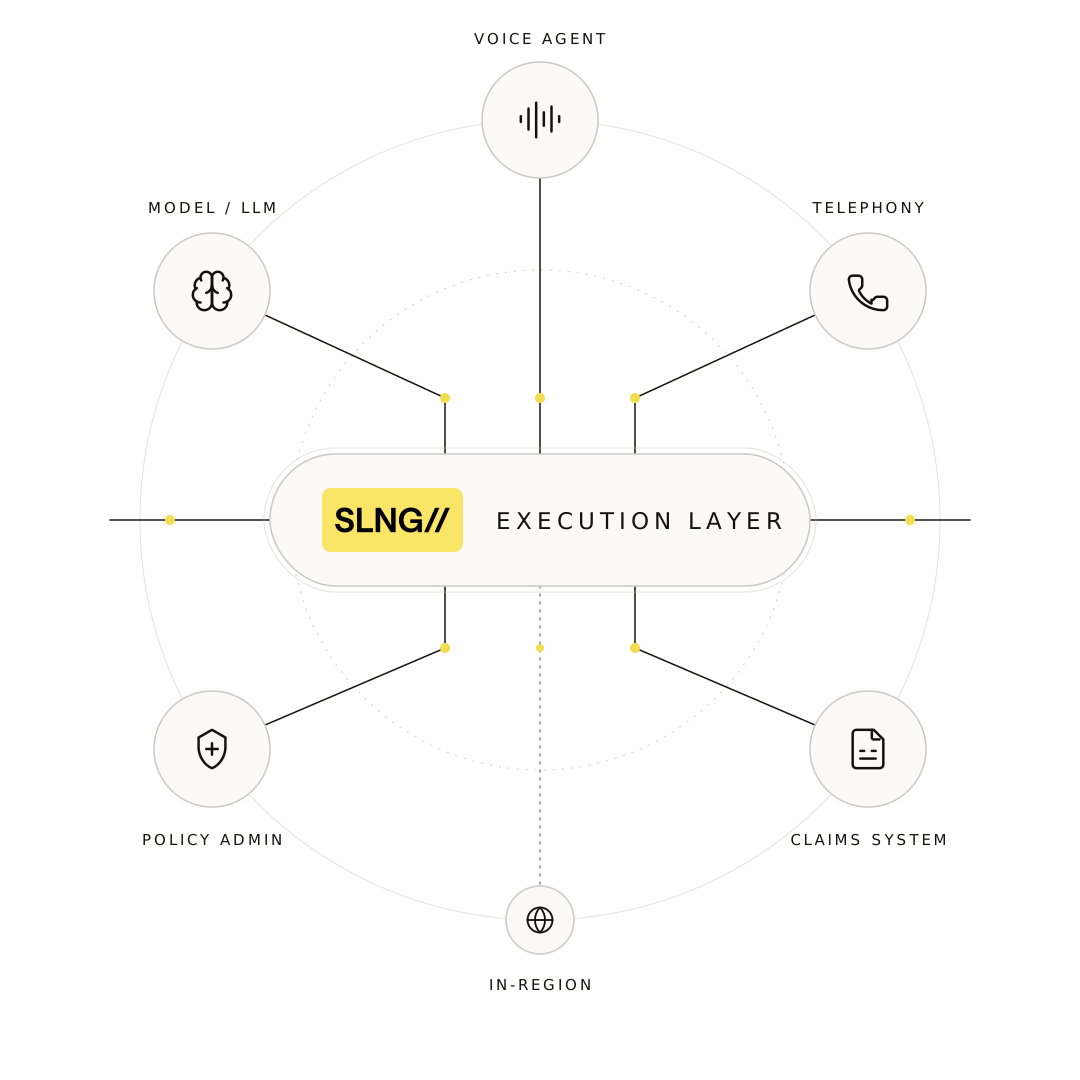
Every call recorded, every turn auditable. In-region execution enforced at the routing layer.
Claims intake and FNOL
Capture structured claim data via voice from first notice of loss through status updates and document follow-up. Voice agents that validate policy details in real time, route to claims systems, and produce exportable audit logs for every interaction.
Policy servicing
Handle policyholder inquiries at scale. Coverage verification, endorsement changes, billing questions, renewal reminders, and account updates. Voice agents integrated into policy administration systems with full call transcription.
Underwriting support
Automate intake for new applications. Capture risk information, verify identity details, and structure responses for underwriting review. Voice agents that collect structured data and push it into submission systems without manual re-entry.
Renewal and retention
Proactive outbound calls for upcoming renewals. Capture policyholder intent, offer retention terms, and confirm coverage changes. Voice agents that trigger from policy management systems based on renewal dates and lapse risk signals.
Continuous optimization
STT model selection · Inference tier routing · TTS path optimization · Regional execution
Adaptive Execution layer
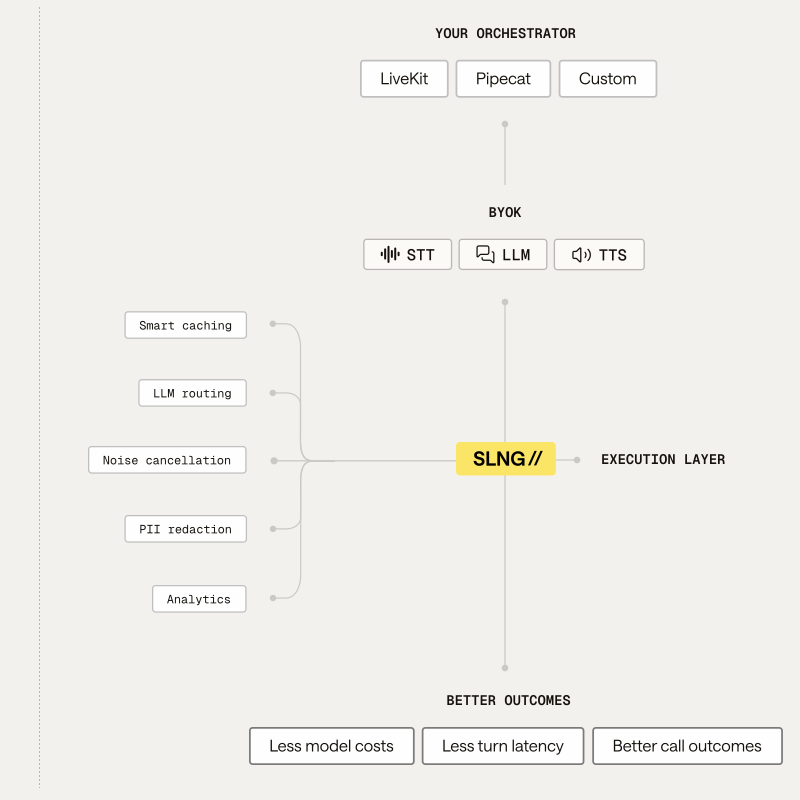
Keep your pipeline. Add the execution layer
The perfect execution path for every turn.
LLM routing
Per-turn model selection and cost optimization.
PII redaction
Personally identifiable data stripped before it leaves the hub.
TTS smart caching
Repeated TTS responses served from cache. Provider never gets called.
Compliance and security


Pricing
Under 1¢ per agent minute
US$ 0.0099 full stack. Or choose your components.
STT
US$ 0.0033 / agent minute · All models included · Or BYOK and pay your provider directly
Execution layer
US$ 0.0033 / agent minute · LLM routing · Smart caching · PII redaction · Analytics
TTS
US$ 0.0033 / agent minute · All models included · Or BYOK and pay your provider directly
Does SLNG work with my agent platform?
If it has a custom LLM field or accepts an OpenAI-compatible endpoint, yes. ElevenLabs, Deepgram, Vapi, Vocode, Bolna, Voiceflow confirmed.
How does latency improve?
Simple turns skip the LLM round-trip entirely. 39% less turn latency on average.
Is SLNG data-compliant?
SLNG is ISO 27001 and SOC 2 Type II certified. HIPAA compliant. GDPR compliant. PII redaction built in.
Does my voice AI data stay in-region?
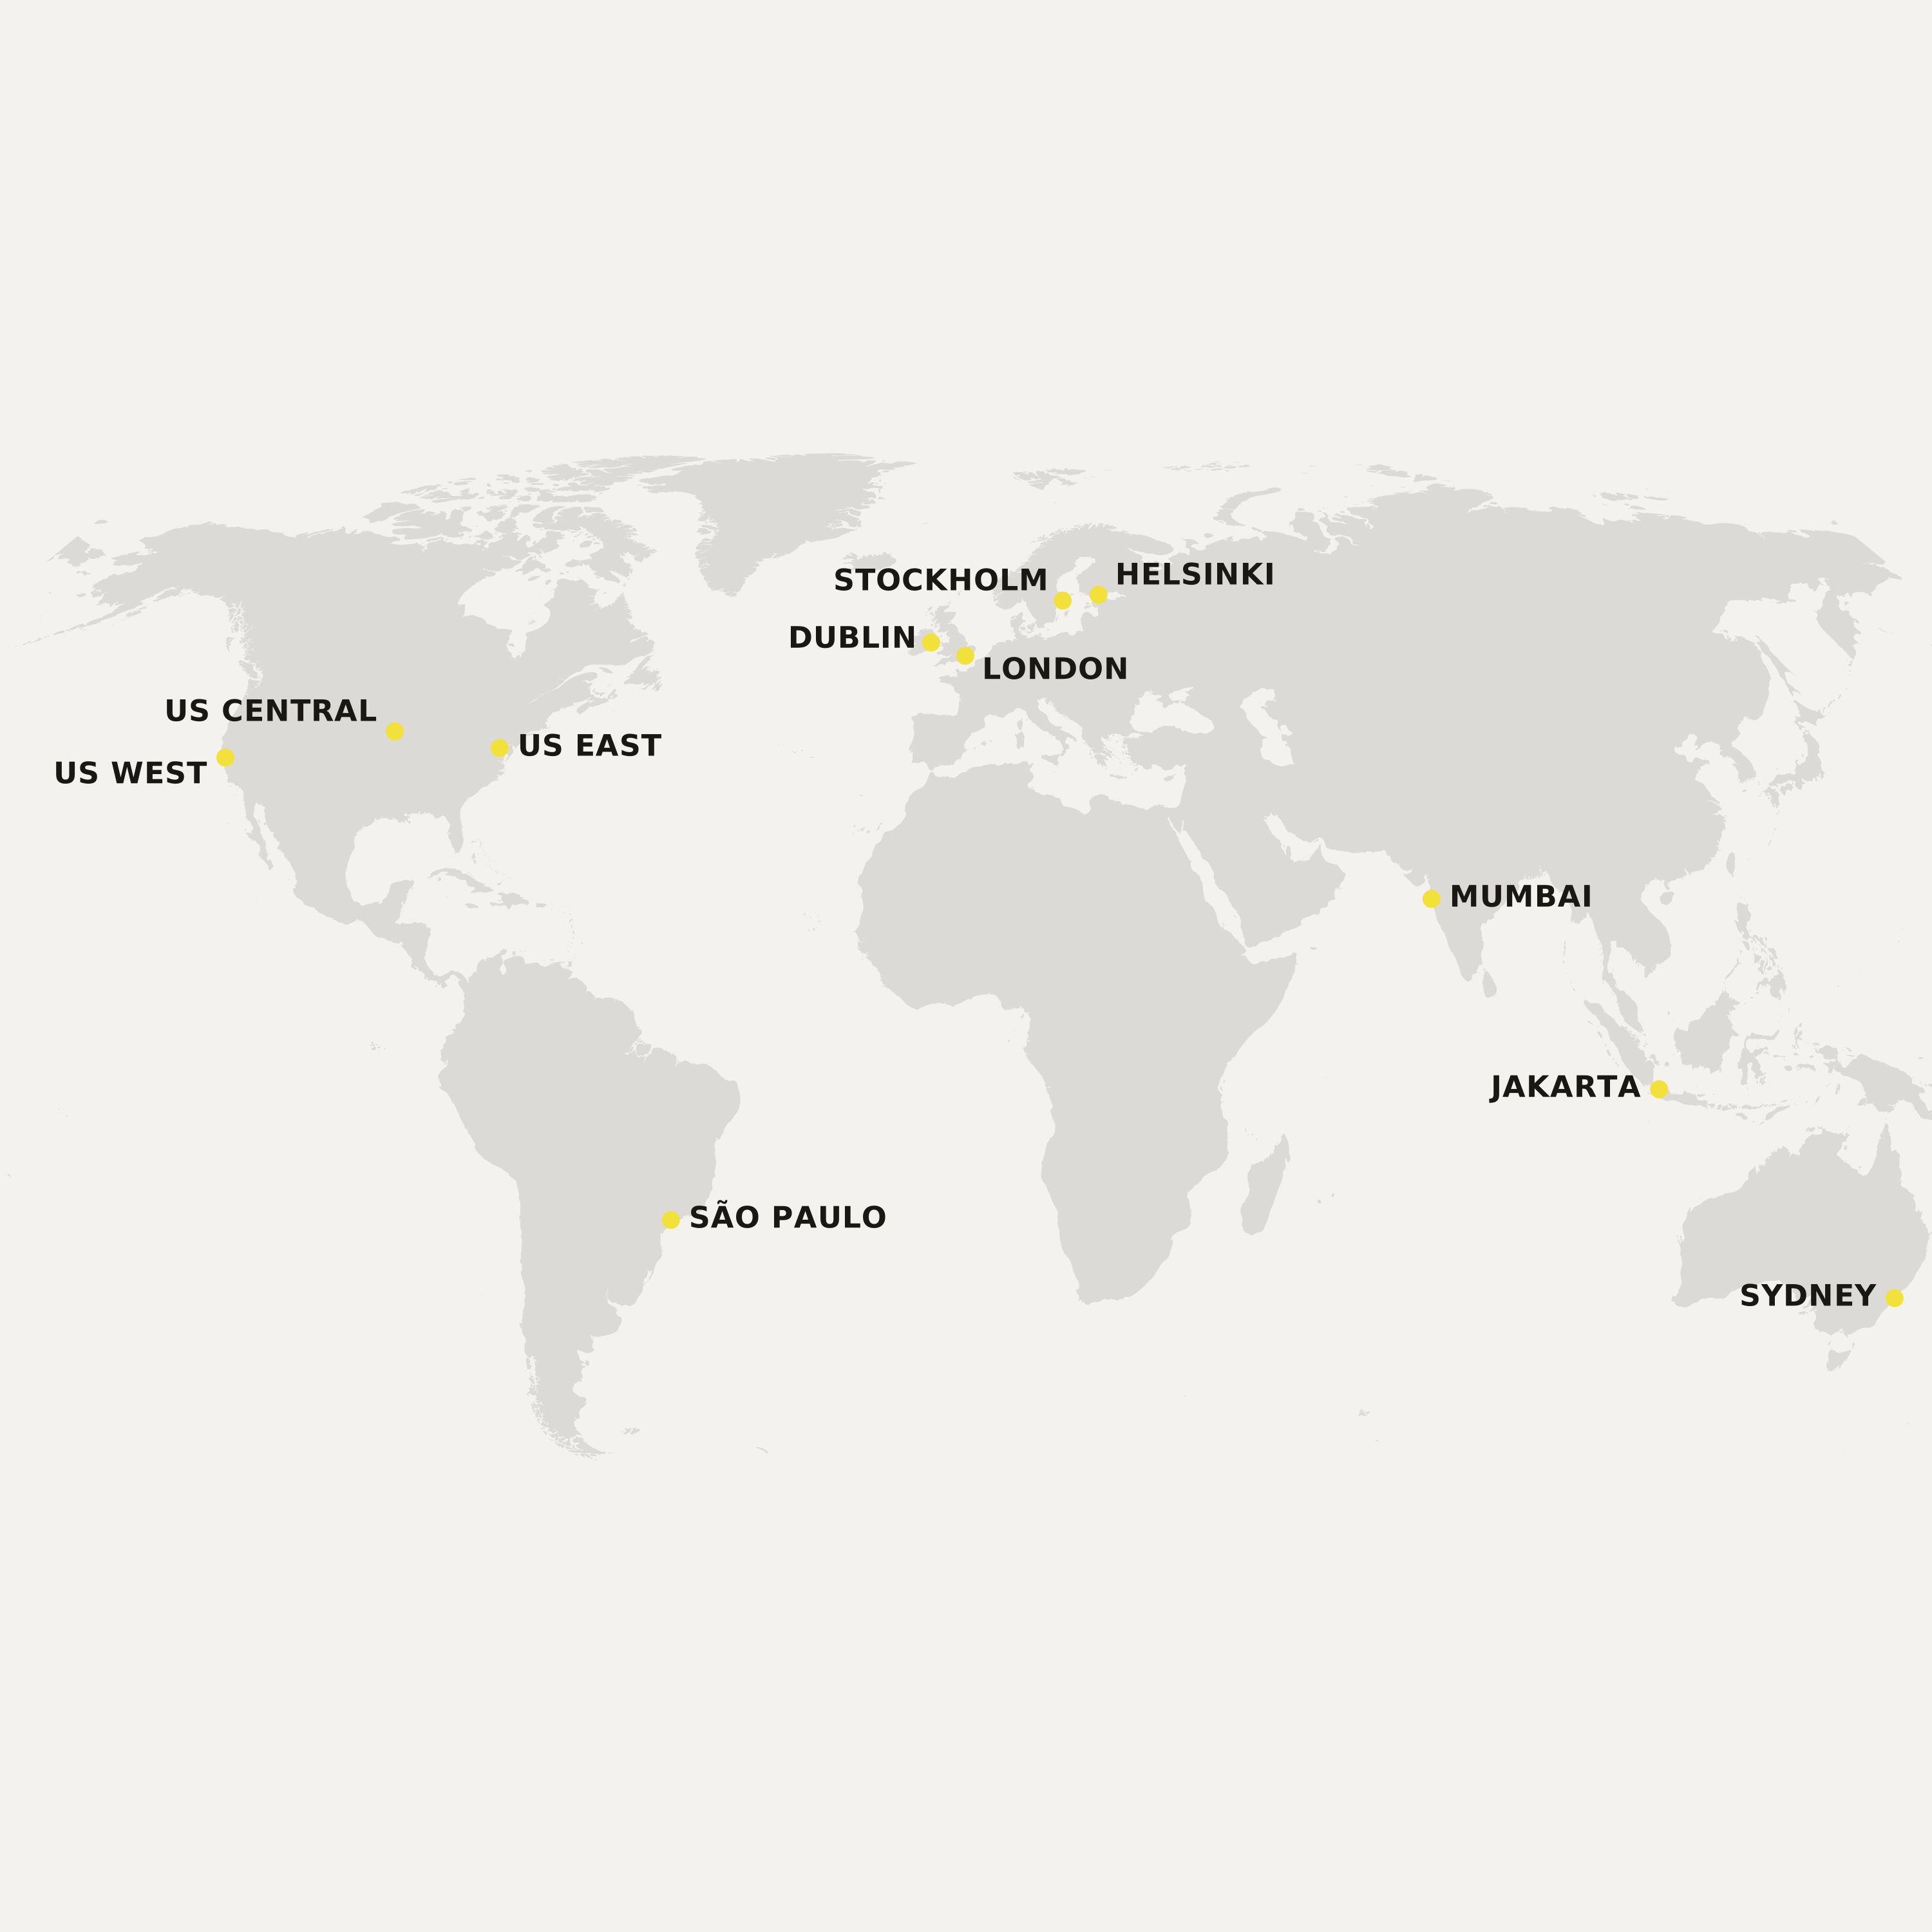
Yes. Audio processed in a region stays in that region. Every call is logged with region, provider, model, and timestamp. You swap your base URL to the region of your choice.
How do I select a region?
One header: X-Region: ap-south-1. Add it to any API call. Same endpoint, same models, different physical location. No DNS changes, no separate deployments.
What does "per agent minute" mean?
Agent minute is the length of the call, not the amount of audio processed. A 3-minute call is 3 agent minutes regardless of how much silence or overlap it contains.
How do I integrate SLNG with my voice AI stack?
Swap your STT, LLM, and TTS endpoints to SLNG. No changes to your orchestrator, your models, or your agent logic. Works with LiveKit, Pipecat, Cognigy, or any custom stack.
Is SLNG compliant with GDPR?
GDPR compliant. ISO 27001 and SOC 2 Type II certified. HIPAA compliant. Details at trust.slng.ai.


